01 · Optimize
Tune a model for a specific GPU and latency target
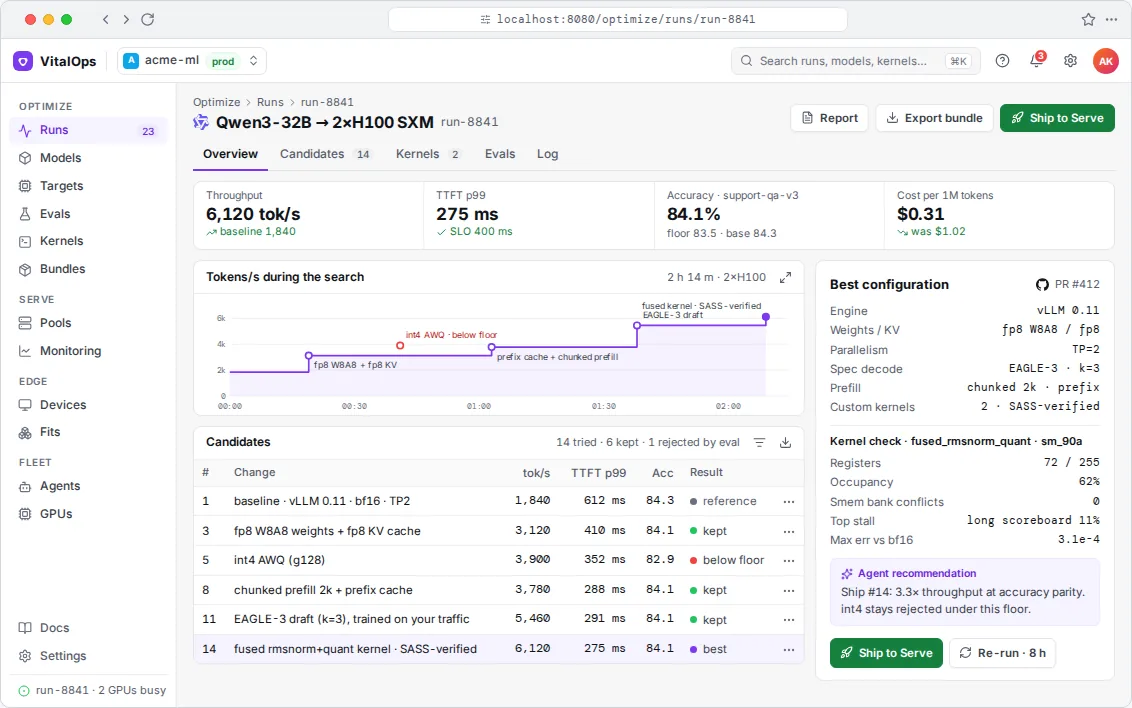
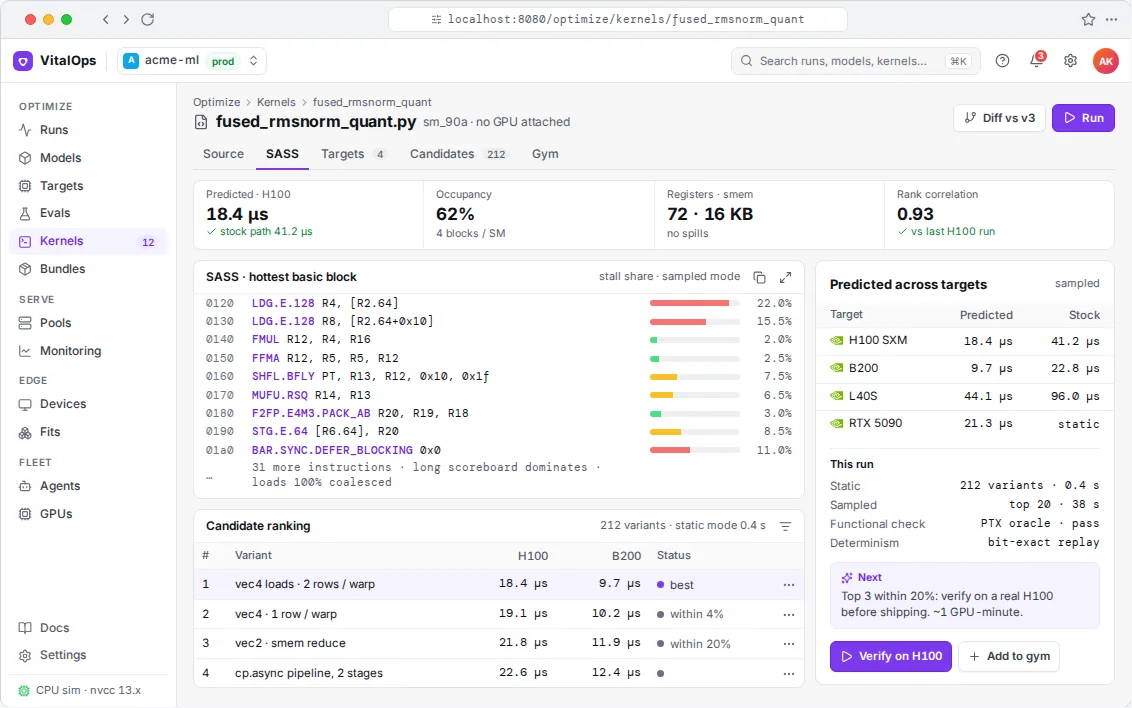
You give Optimize a model, a target GPU, a latency target and an eval set. It tries different engine settings, quantisation, parallelism, scheduling, speculative decoding and custom kernels, ranks the candidates in a simulator, then benchmarks the best ones on real GPUs. Any candidate that scores below your accuracy threshold is dropped. Kernels are checked numerically and at the PTX and SASS level. The result is saved as a bundle you can rerun.
What changes
- One run and a report instead of weeks of manual tuning.
- Each speed-up is reported with its accuracy score.
- Anyone on the team can rerun the bundle and get the same result.
Works with
vLLM, SGLang, TensorRT-LLM, llama.cpp, Hugging Face Transformers; lm-eval or your own evals. Targets: tokens/s, TTFT, TPOT, p99, memory, cost per million tokens.